1. The questions
We use the questions your customers ask, in their language, with your city written into the question: “Can you recommend a good dentist in Austin, TX?”, “Wer ist ein guter Scheidungsanwalt in Wien?”. Each report uses at least two category questions and one question about your business by name.
2. Repeated runs on several engines
For each category question we ask ChatGPT three times, Gemini twice and Google AI Mode once, and record Google’s own map results as a benchmark. For monthly measurement we use five runs on ChatGPT and three on Gemini. We read the answers people see in the apps, not developer APIs, in our tests the two named mostly different businesses.
3. How we report it
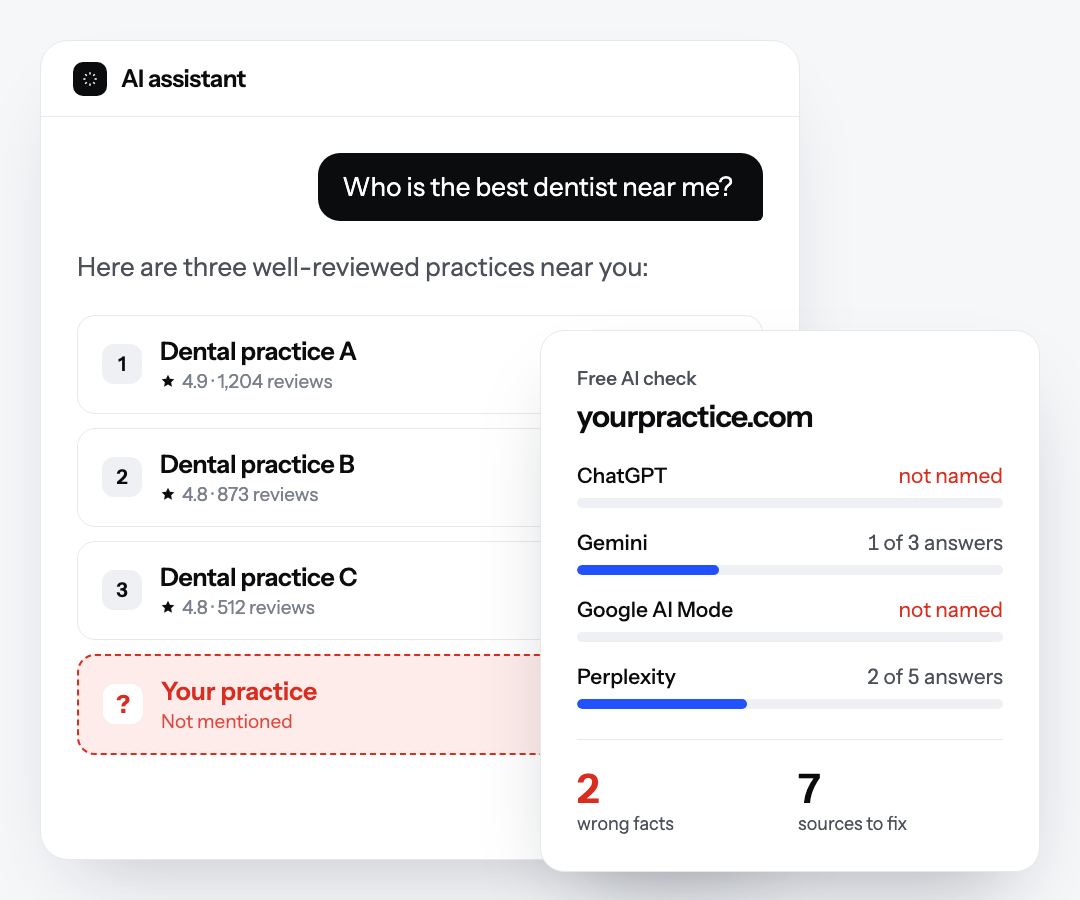
As a fraction with a date: “named in 2 of 3 answers on 3 October” . Never as a percentage from fewer than three runs, never as a “rank”, and never as “you are invisible in AI”, a single missing mention isn’t proof of that.
4. Evidence labels
| Label | Meaning |
|---|---|
| Verified | Machine-checked and reproducible: a file, a status code, a markup error. |
| Seen once | Observed in one AI answer or one search. True for that moment; may change. |
| Unknown | Sources contradict each other and we can’t tell which is right. |
| Not checked | We had no access or no reliable way to check it. Always listed in the report. |
5. Every number has a source
Each report is built from a ledger of facts with the raw evidence behind them. The text is written from that ledger only, and checked automatically: a number that isn’t in the ledger stops the report. External statistics on this site come from named studies with a date and sample size; vendor studies are marked as such.
6. What we can’t see
Answers for logged-in users, paid plans, a person’s own location or chat history; engines we don’t probe (Copilot, Claude, Grok). We say so in every report.
7. Our research
We publish what we measure across industries and cities: How AI recommends local businesses.